Building Beezi AI: Turning AI adoption into measurable engineering performance with the Claude Agent SDK
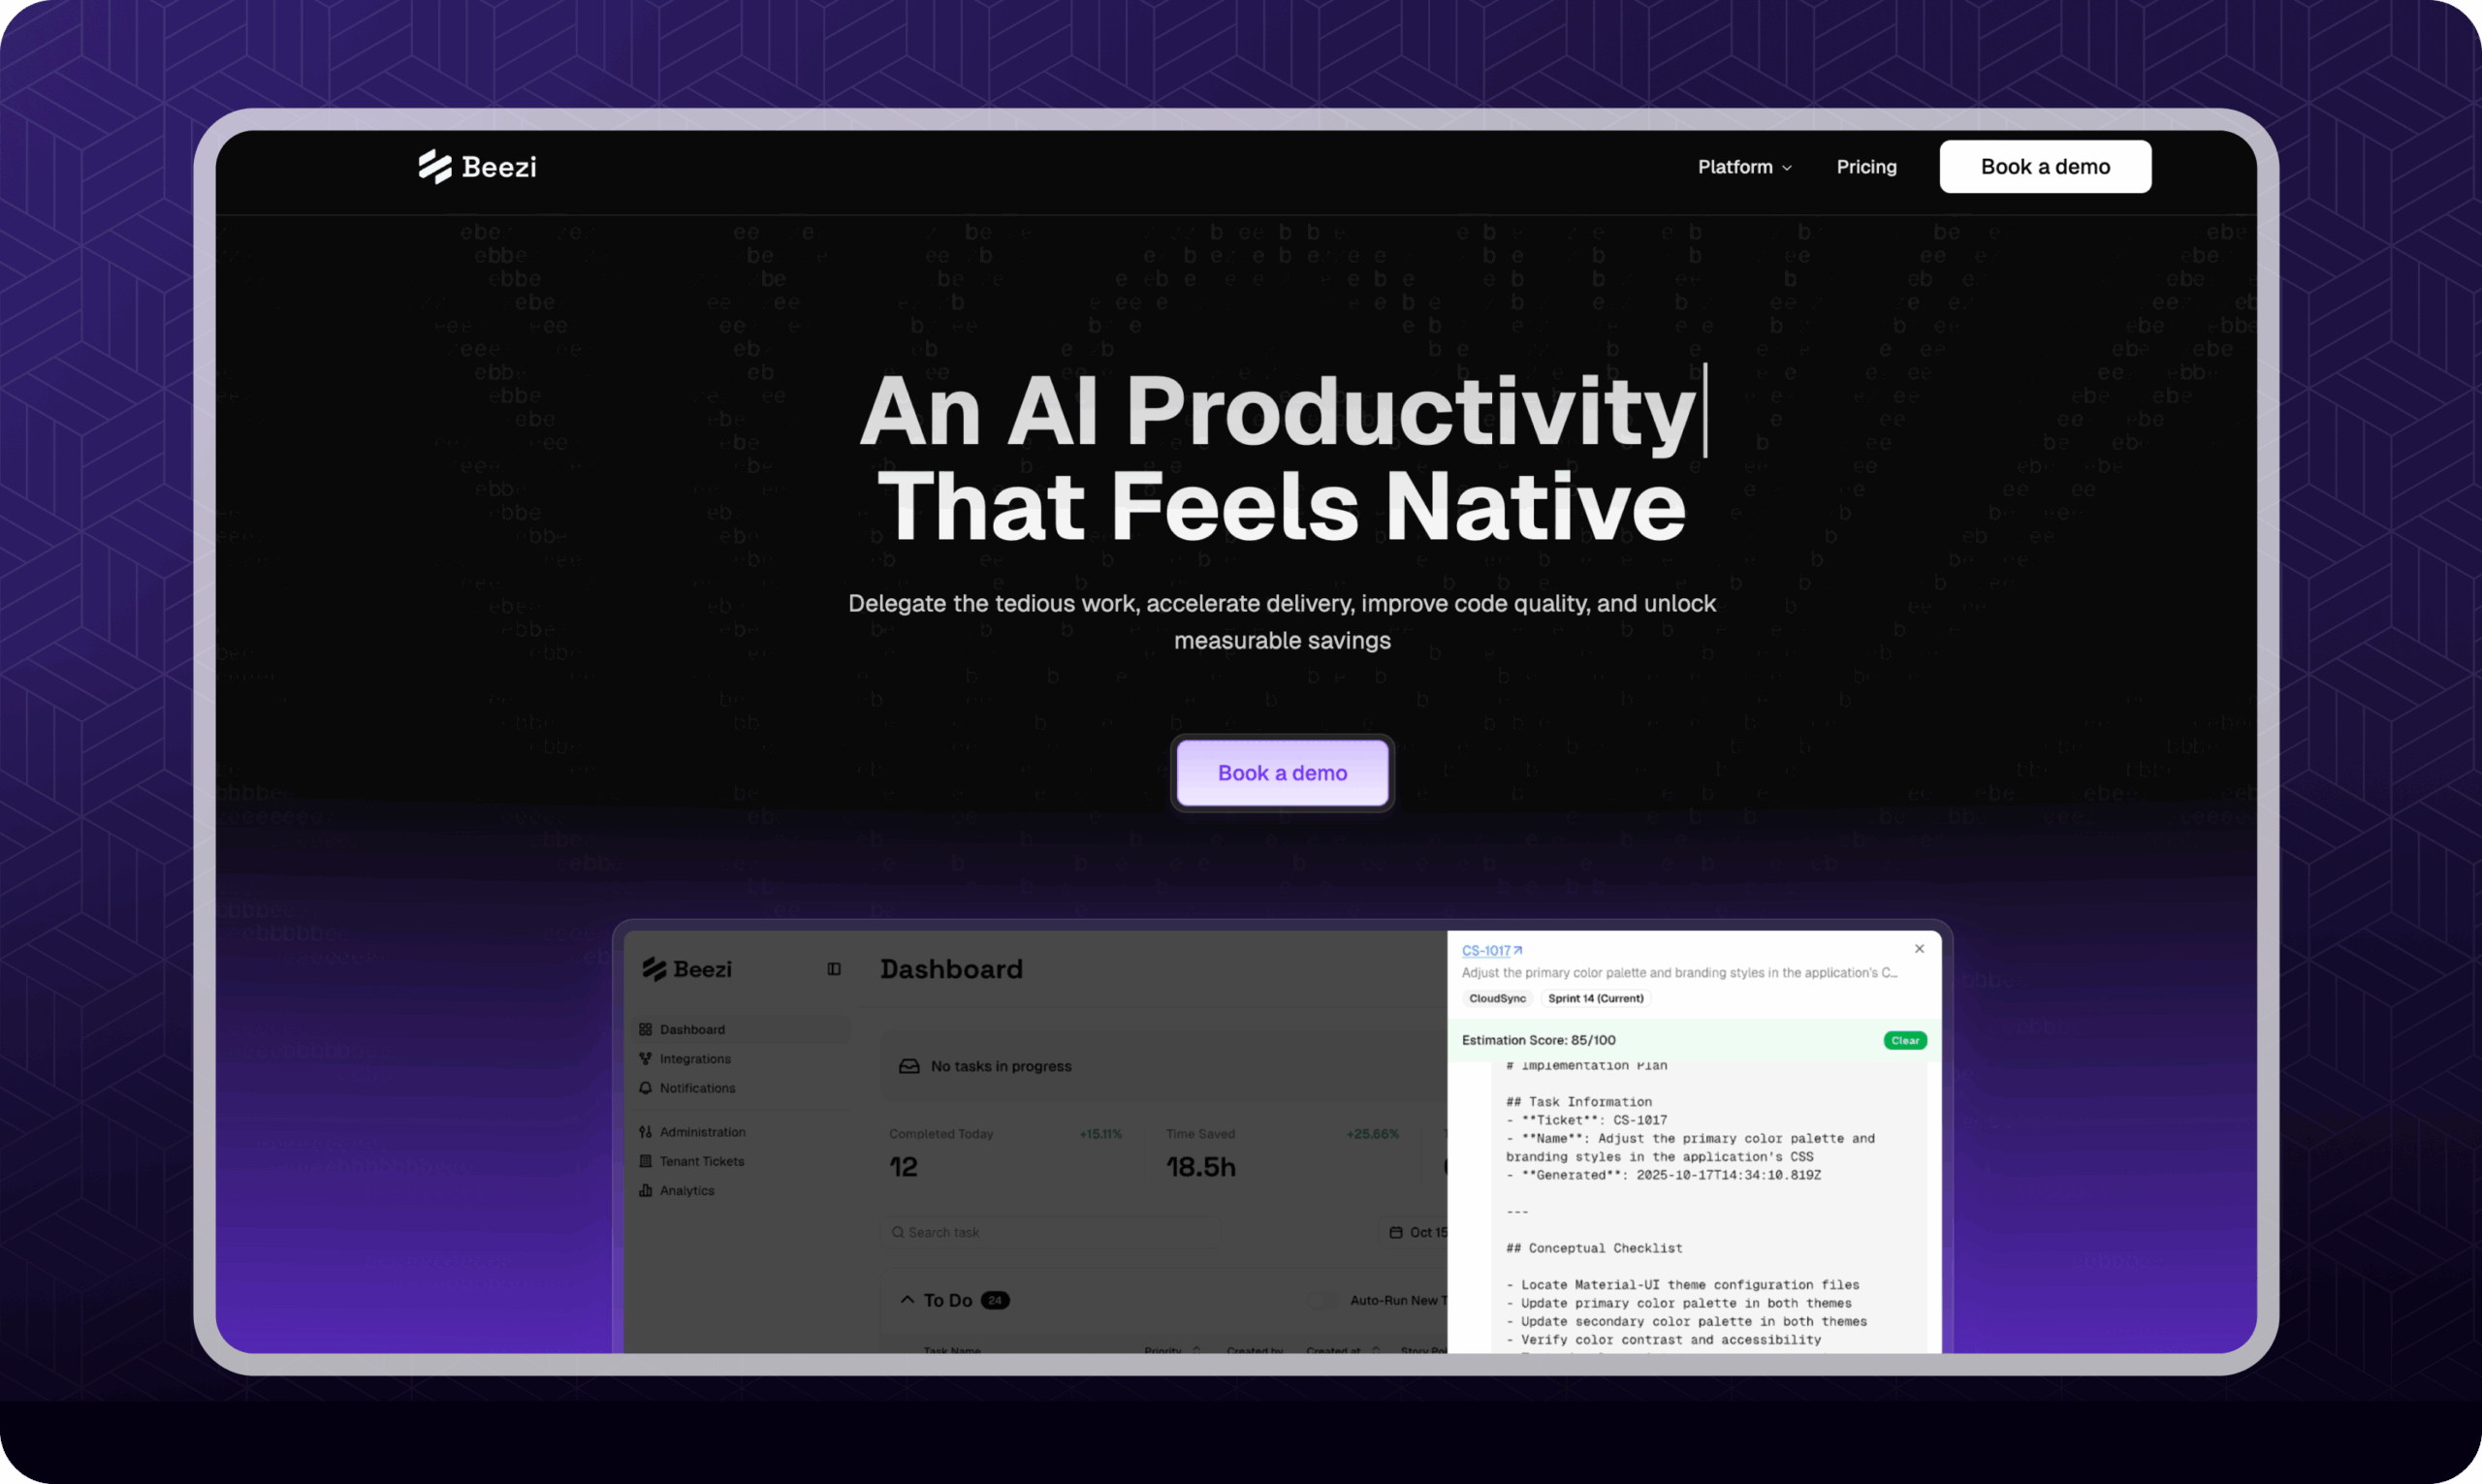
Beezi is a SaaS company building Beezi AI, a multi-agent platform that operationalizes AI-powered software engineering at scale — a chain of specialized AI agents, each stepping in at a different stage of the delivery pipeline, from ticket clarification through implementation to pull-request review.
Honeycomb Software helped Beezi build and scale that pipeline.
Beezi’s product is built on the Claude Agent SDK, with Claude models standardized across the coding-related stages of its multi-agent pipeline, and Honeycomb developed it end-to-end using Claude Code.
Delivery. AI tools were already in daily use across the team, but adoption had happened tool by tool and engineer by engineer. Cursor, GitHub Copilot, and assorted assistants ran side by side, each with its own configuration and its own rule files. One engineer maintained a detailed Cursor ruleset; another worked in a different tool, never saw those rules, and wrote their own. Conventions lived in personal setups instead of the repository, so nothing propagated: a rule fixed in one place stayed fixed only there.
The consequences compounded as the codebase grew. Output quality depended on which tool an engineer happened to use and how well they had configured it. Research, verification, and review had no shared standard, so nothing distinguished a checked answer from an assumed one. Context accumulated in individual chat histories and left with the person who owned them. No one could measure whether AI was improving delivery because no two engineers were doing the same thing.
Product. The pipeline faced the same problem in its architecture. Beezi’s vision was a chain of specialized agents, each owning a stage of the delivery process, but the foundation it had been prototyped on wasn’t built for that model. Agents produced inconsistent output from stage to stage, and every new stage introduced regressions in existing ones instead of extending them cleanly.
Both problems had to be solved against a fixed team: 2 engineers from Honeycomb Software side, no plans to hire, and a roadmap that required research, implementation, and continuous refinement across every stage.
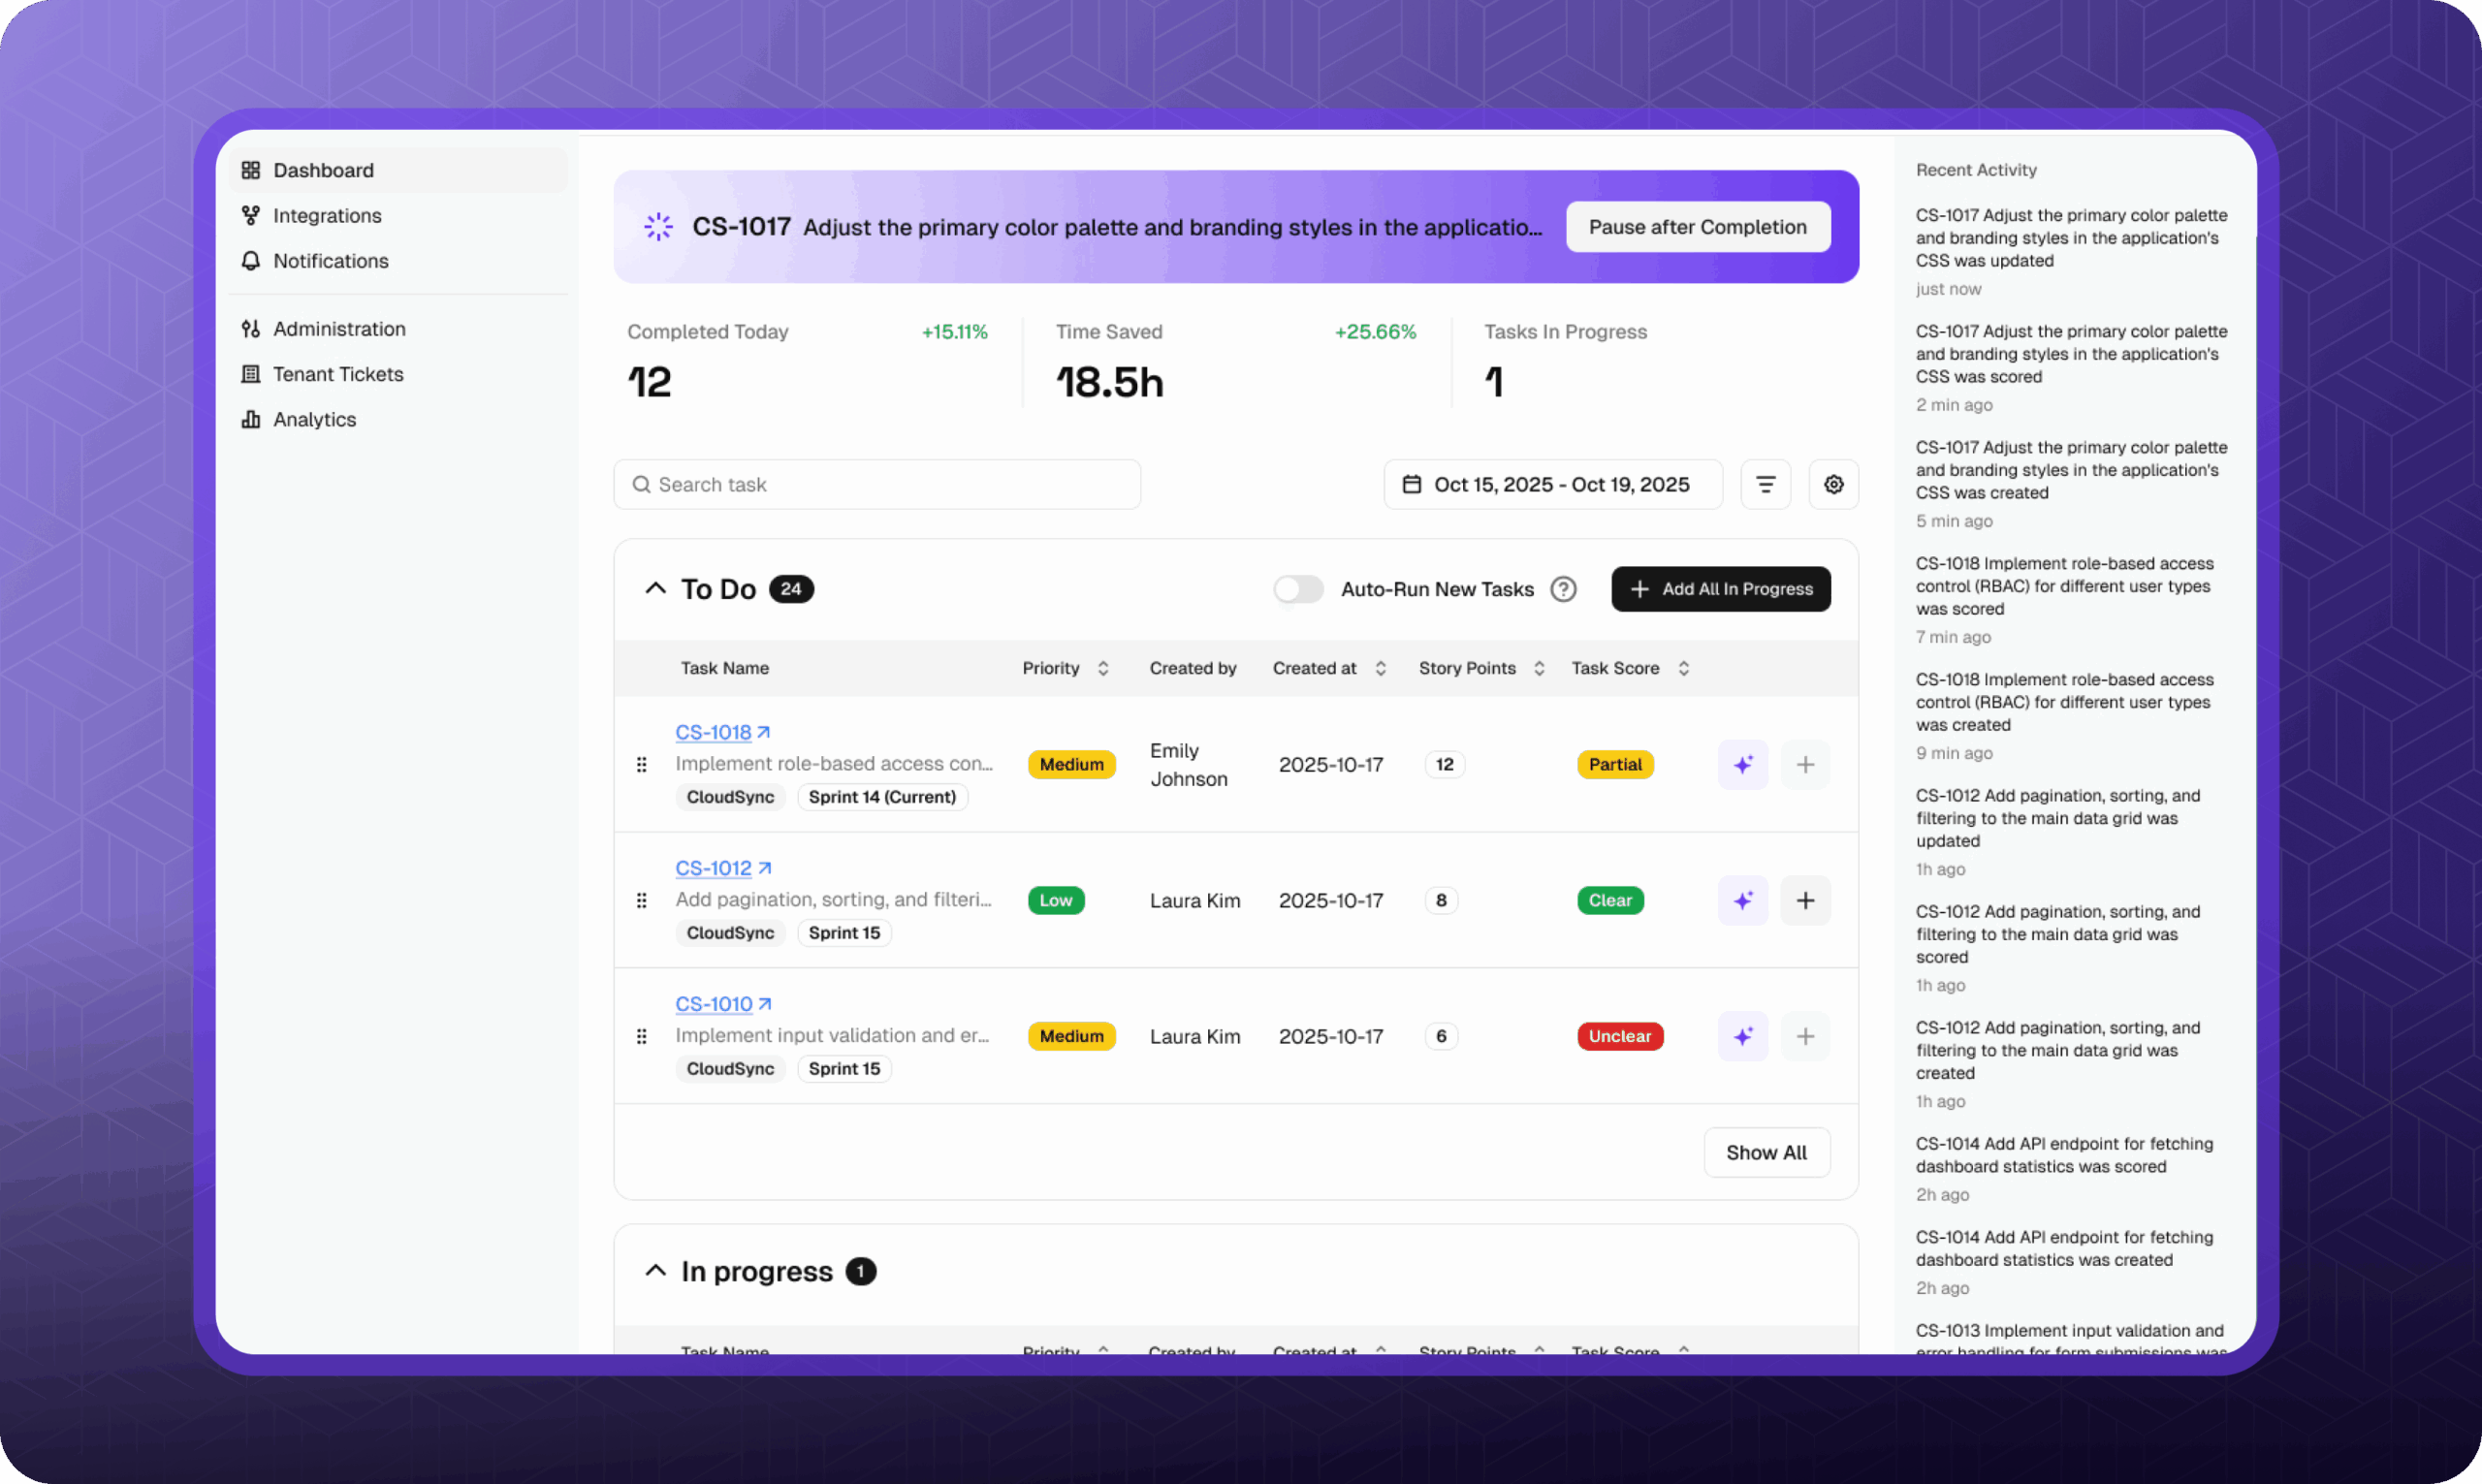
Architecture. Honeycomb’s recommendation was consolidation on both sides. The team standardized on Claude Code as a single agent environment, with conventions moved out of individual tool configurations and into the repository, where they are versioned with the code and applied to everyone. The product itself was rebuilt on the Claude Agent SDK, so every stage of the pipeline extends a shared foundation rather than a per-stage implementation. The recommendations covered architecture, research, clarification, shared context, review, and model choice, so that every change goes through research, clarification, planning, implementation, and review, each handled by an agent with a clear job.
The team standardized on Claude models for every stage, each matched to its job on quality, speed, and cost:
- Claude Opus handles clarification, estimation, and planning, where a wrong answer costs more than tokens.
- Claude Sonnet generates code and updates pull requests, balancing quality and speed.
- Claude Haiku 4.5 takes high-volume, low-risk calls, such as summarizing MCP tool lists, checking that a customer’s MCP servers work, and diagnosing errors.
Model choice is only part of the setup. Reasoning effort is set per model in the portal. Models are compared on an internal benchmark harness, a graded ladder of tasks from trivial to extreme with cost and turn budgets, which a Claude judge scores on correctness, quality, and efficiency.
- Each change gets its own working folder. When an agent finishes a step, it summarizes its work in a short report: what it changed, the facts it verified, the decisions it made, and anything it deferred or found blocking. The coordinator turns that report into a brief for the next agent, which carries forward only the key decisions, verified facts, and constants (the branch to work on, frozen contracts, known baseline test failures, commands that must never run) instead of the full transcript. A shared constraints file binds every step, and a progress file records which steps are done, how each was verified, and what is still open, so any agent, or a fresh session after a context reset, picks up exactly where the last one stopped. Agents keep scratch files for intermediate notes and analysis outside the codebase.
- Guardrails: People stay in control at each hand-off. When a ticket scores below the clarity threshold, the agent asks the team questions instead of guessing, and implementation starts when someone approves the plan (users can opt in to automatic queuing above a score they choose). Agents open pull requests for review, and only people merge them. Each PR runs separate validation agent that installs dependencies, runs lint, build, and tests, and reviews the code before a person does, and any critical finding fails validation. Hooks limit what agents can do inside a run: the quality pass may edit only files the task changed or created, and fix and subtask agents are blocked from git and pull-request commands. Infrastructure secrets are removed from the agent environment, and role-based access and per-project API-key allowlists control who can run which models.
Built with Claude Code. The team used Claude Code across the full delivery lifecycle, not only for writing code:
- Research and design: Research runs through a hub-and-spoke setup in Claude Code. A coordinator agent breaks a question into parts and sends the team’s own search agents after each one in parallel. The search agents read current library and SDK documentation through the context7 MCP server, search the web, and read the codebase, and a shared library-facts skill makes them cite a source for every claim: the installed package first, then context7, then the web. A second group of agents tries to disprove each finding, and the coordinator merges what survives into a short list of outcomes and next steps. The same pattern runs against the codebase itself. A database performance audit, for example, sent 15 agents across every query path in the API: 60 findings survived verification and 26 were refuted, the coordinator merged them into 55 distinct defects and a prioritized fix list, and the first fixes from that week’s audits merged the next day. Design work moves from brainstorm to written spec to implementation plan, and the platform repository alone has produced more than 380 design specs and 330 implementation plans this way.
- Implementation: Project conventions live in CLAUDE.md files for the platform and each of its packages, mirrored in AGENTS.md so every coding tool follows the same rules. Ten path-scoped rules load only when Claude touches matching code, such as API controllers, persistence, multi-tenancy, or client UI. Repeatable procedures, such as database migrations, are packaged as skills. Larger changes run as subagent-driven development: a coordinator splits the plan into bundles by file ownership, parallel subagents implement each bundle in its own git worktree, and an independent reviewer checks every bundle before integration. In one run, 28 agents worked through 34 issues across two repositories in about an hour.
Quality: Pre-commit hooks run ESLint, Prettier, and TypeScript type checks on staged files in the platform, and Ruff and Pyright in the Python agent service, so Claude-written code clears the same checks as human-written code. A shared verification rule tells Claude to trust exit codes and compiler output over its own reading of the code. - Code review: Automated review agents in the pull-request workflow assess code quality, catch bugs, suggest fixes, and clarify tasks before implementation starts. In the product they are built on the Claude Agent SDK: Beezi’s clarification agent questions unclear tickets before any code is written, and its validation agent reviews generated pull requests and sorts findings into critical, warning, and good-to-fix, each with a suggested fix.
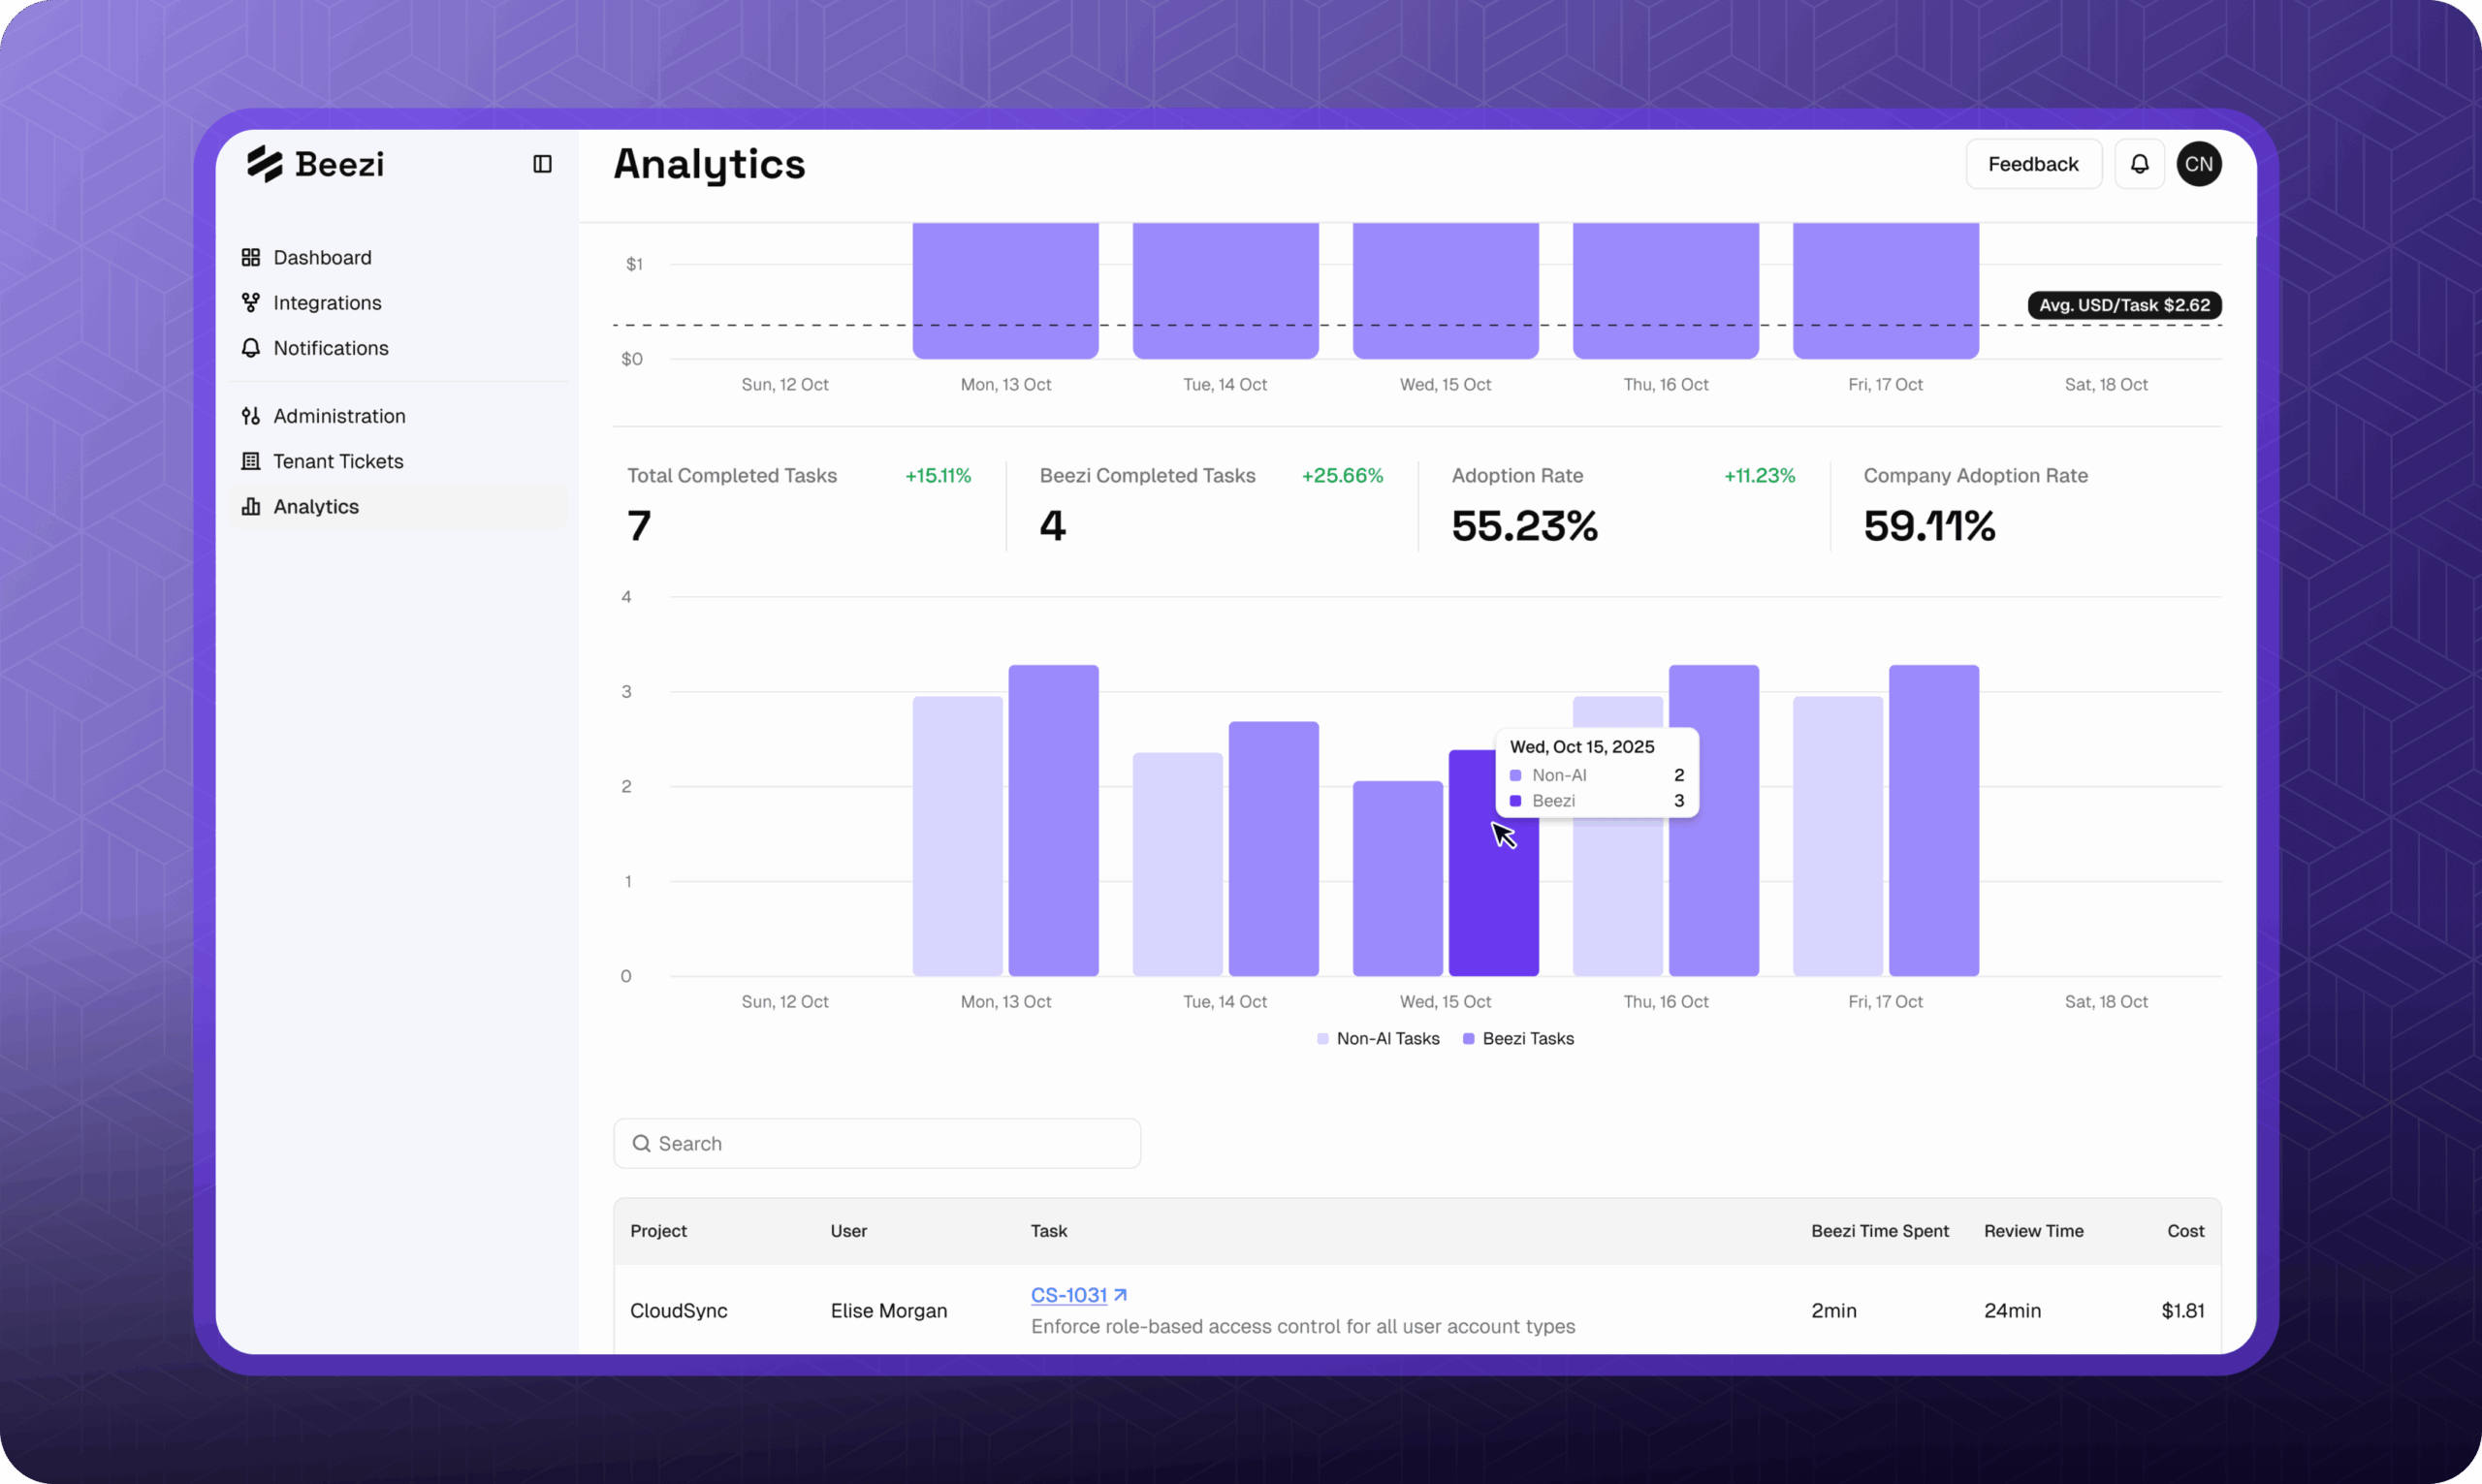
- Production in ~4 months, from architecture decision to live release in January 2026
- Built by 2 engineers, with no additional hires across the whole build; development velocity by approximately 40–60%
- Paying customers since April 2026, running Beezi AI against their own delivery pipelines
- Every change goes through research, clarification, planning, implementation and review — 380+ design specs and 330+ implementation plans in the platform repository over five months
- No AI-written code reaches production unreviewed: an automated validation agent checks every pull request, and only people merge
- The team estimates delivery ran 2–3× faster than a conventional approach would have allowed
Claude remains embedded in Beezi’s day-to-day development, and the core team ships new features and platform improvements without growing.
Get in touch with us!
We’ll review your message and get back to you soon.
In the meantime, feel free to explore our case studies or submit another request.